Building Blobber to back up my own databases
GW2.FR’s MySQL database has been backed up every few hours for over 10 years at this point. Back then, I had written a simple shell script extracting the database credentials from the Django settings directly, and running mysqldump.
Here is the core of it, which was then published as a gist:
#!/usr/bin/env bash

set -euo pipefail

# Fetching MySQL credentials in Django's settings file
CREDENTIALS=$(python3 -c "
from $SETTINGS import DATABASES
db = DATABASES['default']
print('-u {0} -p{1} {2}'.format(db['USER'], db['PASSWORD'], db['NAME']))")

DUMP_DIR="$DIRECTORY/$(date +"%Y/%m/%d")"
DUMP_FILE="$NAME_PREFIX-$(date +"%Y-%m-%d-%Hh%M").sql"

mkdir -p "$DUMP_DIR"

mysqldump $CREDENTIALS > "$DUMP_DIR/$DUMP_FILE"
GW2.app was releasing in February 2026, and backups were needed before launch. It keeps its user data in PostgreSQL and its game data in a SQLite database on the side, so my old script was of no use there. The dumps also never leave the machine, nothing compresses them and nothing ever deletes the old ones.
I could have added the missing cases and moved on, but one of my university teachers made us repeat “backups are useless if you can’t restore” at the beginning of every class for a whole semester, and that had been a blind spot with the current setup. Applying a backup would mean remembering where the credentials are, and typing the mysql command by hand (not error-prone at all!). I figured both problems could be solved at once.
My thinking: a backup runs unattended every few hours and succeeds silently, so it only needs to be a line in a crontab. A restore is the opposite, because it runs after something has already gone wrong, and that is when I have to remember which flag takes the file name and which of the last thirty dumps is the one from before the incident. A lot can go wrong when it’s time to frantically restore a corrupted or wiped database.
As I started working on the solution to all these problems (which I called Blobber, because I wanted the backups to be saved on some blob storage), I figured both a CLI and a TUI were needed. The CLI is what goes in the crontab (blobber backup, plus list and restore for scripting) and the TUI is what I open when a restore is actually needed. It lists the backups it found, so I pick one instead of typing a file name.
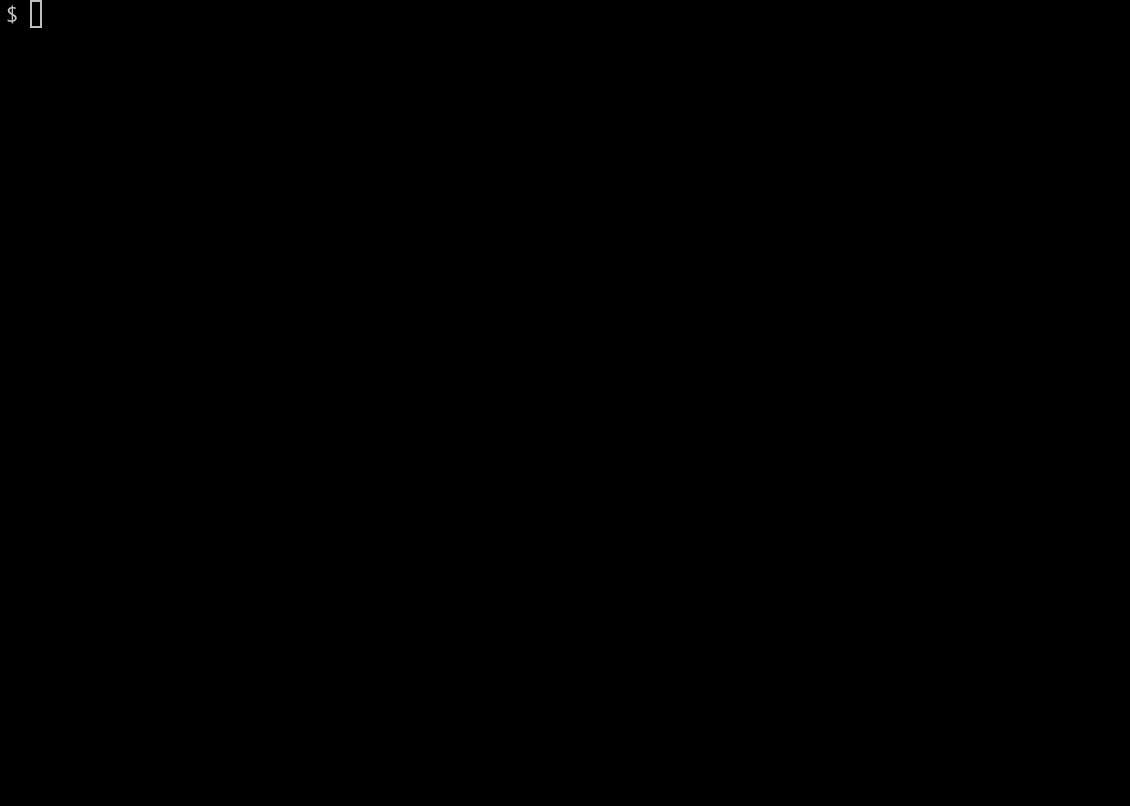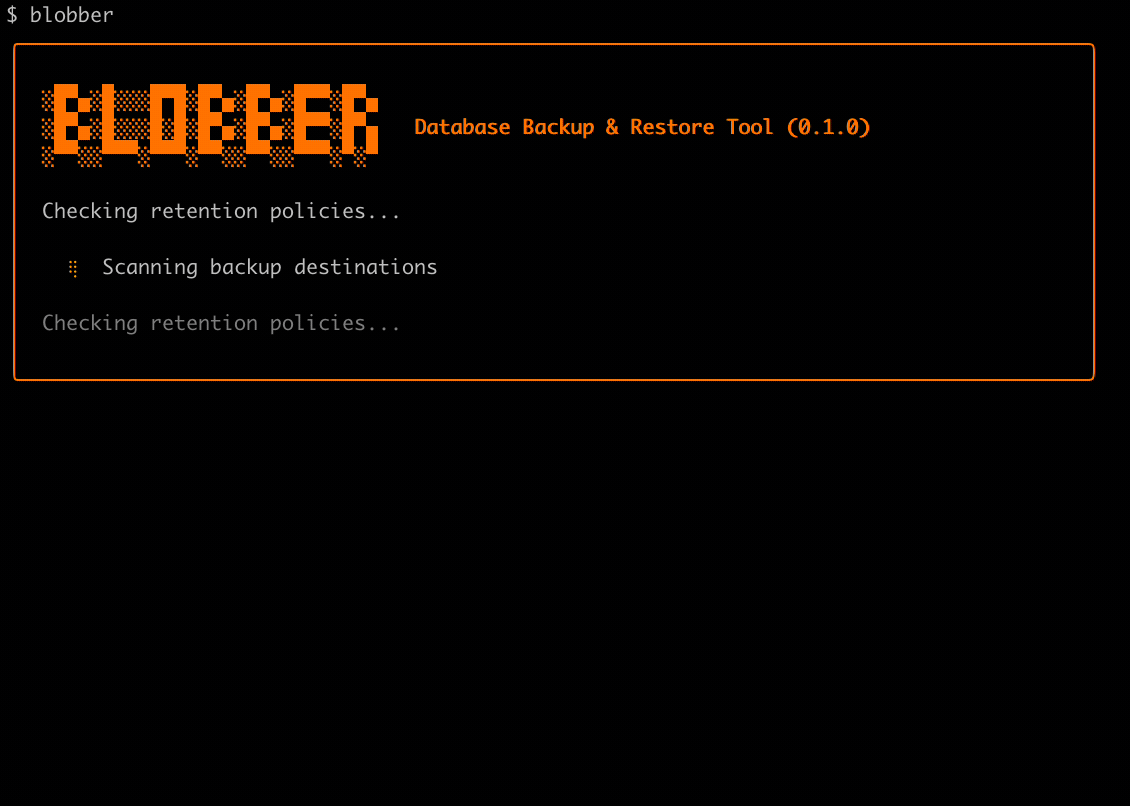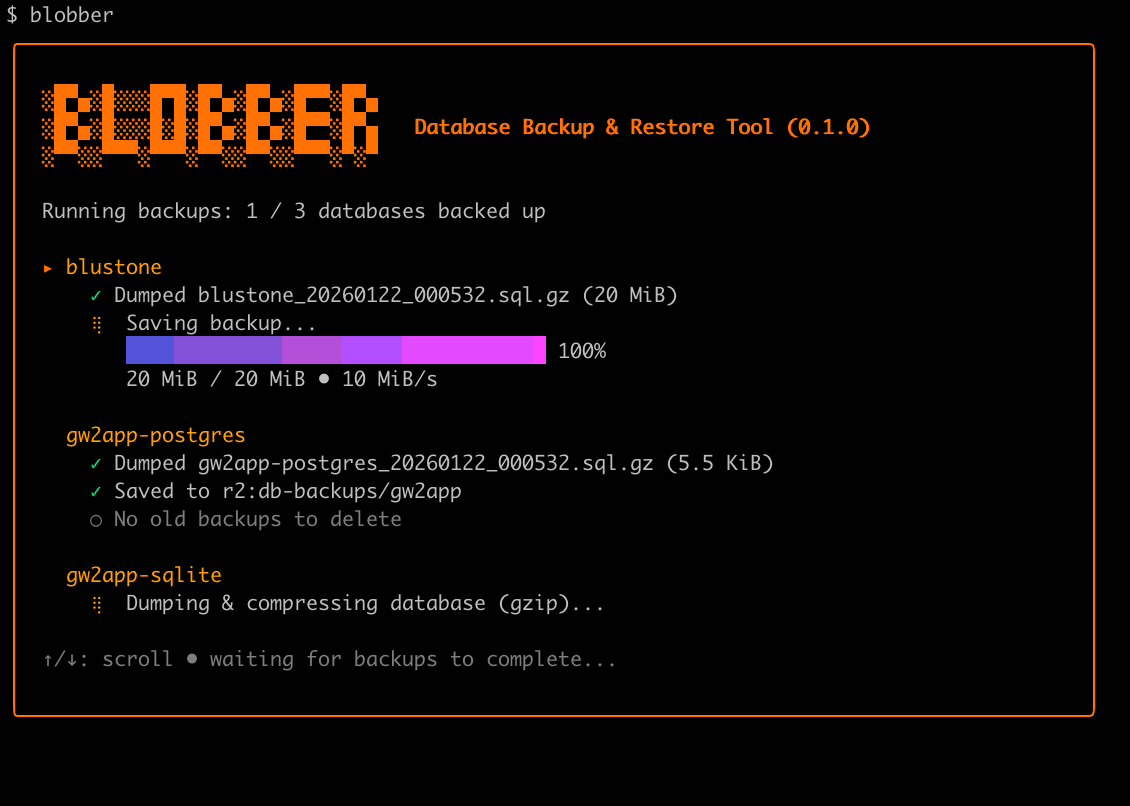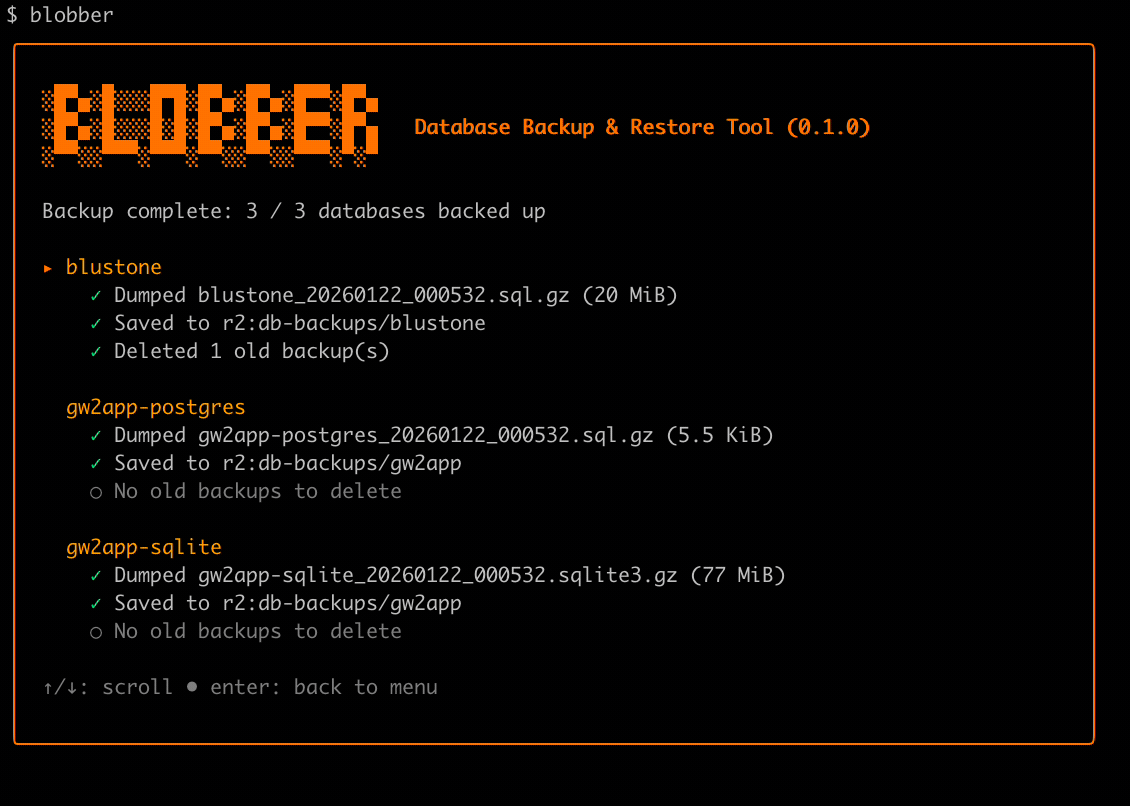
The TUI, with a demo of a manual backup, but the usefulness comes from the guided restores.
All of the config lives in 2 YAML files: the Blobber config for backup rules, and the rclone config for credentialed remotes. For each entry, Blobber runs the database dump tools (mysqldump, pg_dump, or a plain file read for SQLite) and streams the output through a compressor before writing it to the destination (any rclone remote or a local path). None of that needed reinventing, and I didn’t need a scheduler or a daemon either. Blobber bundles rclone in the Go library and finds the backup CLIs in the PATH.
Retention is also pretty simple, with just three rules (keep_last, keep_days and max_size_mb) evaluated against the listing of the destination itself rather than against any local state.
I built it over a weekend in January 2026, as a test drive for a project written entirely by a coding agent, and it has been backing up all three databases ever since. I have tested restores along the way and they all worked without a hitch.
The code is available on GitHub.